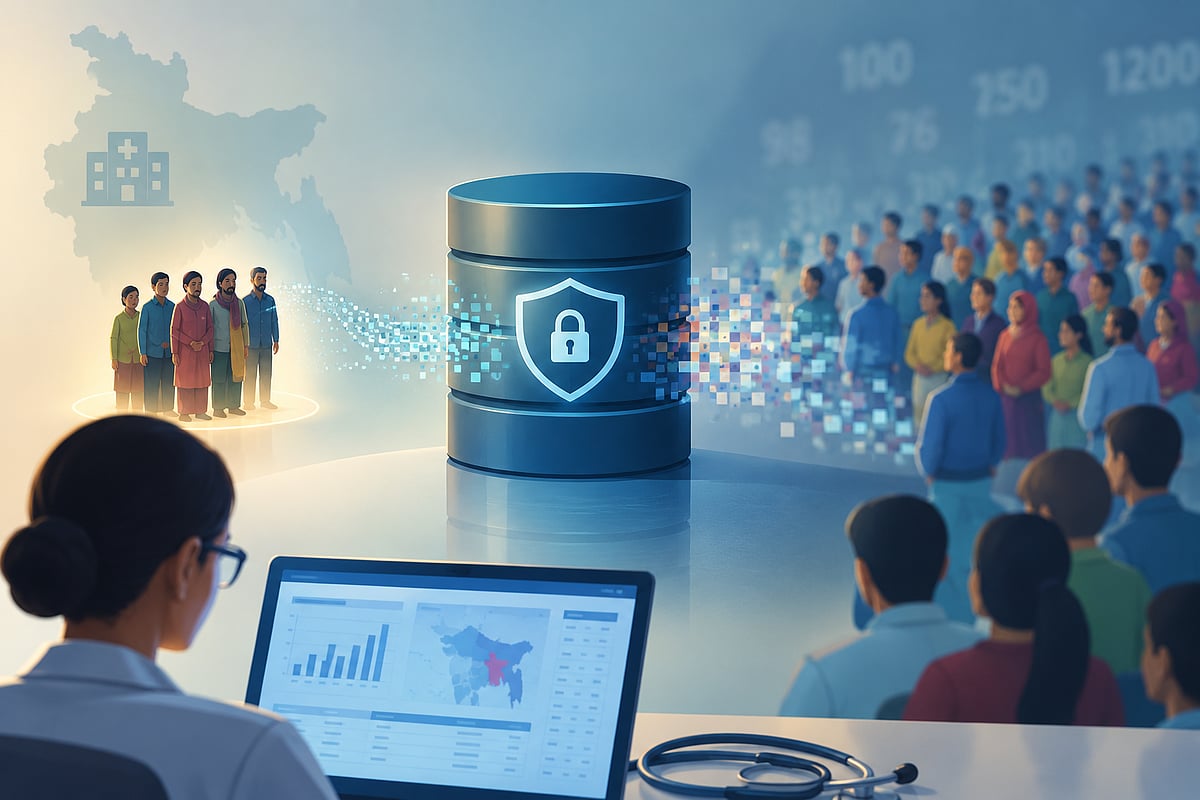
Imagine a national health database where only seven or eight patients in a particular district are diagnosed with a rare and complex condition in a given year. The number is remarkably small, but for those seven or eight individuals, it is their entire reality. Now, imagine a mathematical mechanism implemented within this database to protect patient anonymity, designed to inject a slight degree of random 'noise' into every recorded figure.
For large populations, this noise is practically negligible. However, for small figures like seven or eight, this minor distortion can completely swallow the actual data. The database remains securely confidential, but the patients of that district are rendered virtually nonexistent on paper. This phenomenon has a formal name: differential privacy. American computer scientist Cynthia Dwork first formulated the concept mathematically in 2006. Over the past decade, it has been widely adopted worldwide for health data, censuses, and even the training of large-scale AI models. The fundamental issue is that the very mathematics meant to safeguard our privacy can completely erase certain individuals from the realm of statistics—a regular occurrence that almost always affects the same marginalized groups.

The mathematical inevitability of this issue is stark. Suppose the number of people afflicted with a rare disease in a specific area is five. Under robust privacy settings, the injected noise could easily skew that number to two or nine.
The core strategy of differential privacy is relatively straightforward: a random number is added to the true answer of a query, ensuring that whether a specific individual's record is present in the database or not, the final output remains largely unchanged.